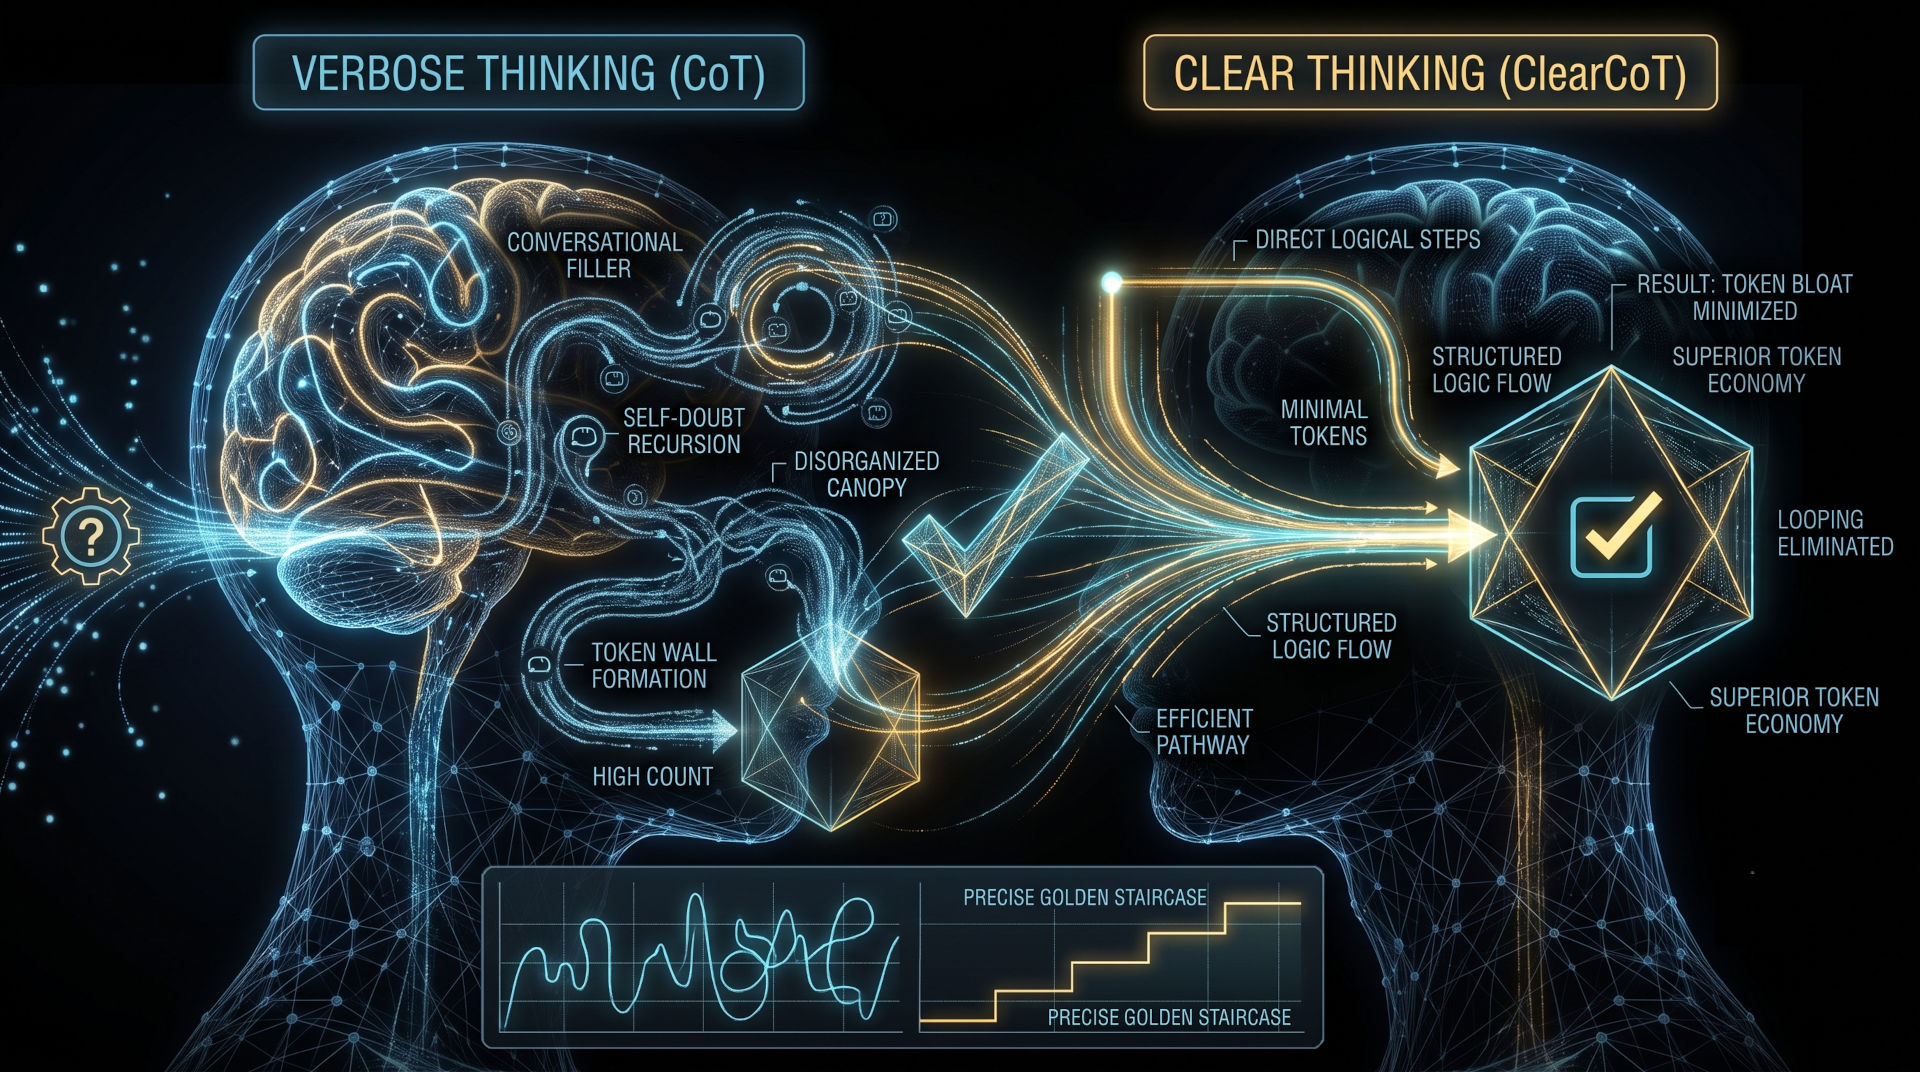
Clear Chain-of-Thought (ClearCoT)
Eliminating the Token Wall: Standard Chain-of-Thought (CoT) reasoning often leads to failure states where models get trapped in endless self-debates and conversational filler.
The MasterMind Model: A 4B-parameter model was trained on philosophical texts to act as a “logical optimizer” tool, restructuring existing datasets to strictly connect the Question, Reasoning, and Answer (Q-R-A).
Efficiency Meets Accuracy: The resulting Occam-2B model increased MMLU-Pro accuracy by 6.71% while eliminating up to 89.4% of wasted reasoning tokens on complex logic tasks.
The Problem: The Conversational Canopy and the “Token Wall”
While Chain-of-Thought (CoT) prompting improves Large Language Model (LLM) reasoning, it mimics human thinking by generating extensive conversational filler. This “canopy-like” reasoning demands massive computational resources and extends GPU runtime.
Worse, it often leads to a “Token Wall” death-loop—a phenomenon where the model exhausts its maximum context window debating alternatives and generating self-doubt, ultimately failing to reach an answer.
The Solution: ClearCoT and the MasterMind Model
Rather than relying on mechanical prompt engineering, the Clear Chain-of-Thought (ClearCoT) methodology starts by distilling philosophical clarity directly into the model. The goal is to enforce a meaningful, rigorous structure between the Question, Reasoning, and Answer (Q-R-A).
The Optimization Workflow
- Foundational Logic: We used a 27B-parameter Teacher model to synthesize roughly 6,000 highly optimized philosophical reasoning pairs based on the Stanford Encyclopedia of Philosophy.
- Training the MasterMind: A 4B-parameter model was fine-tuned on this dataset to become a specialized “logical optimizer”.
- Dataset Adaptation: The MasterMind model restructured general datasets (like Nemotron-Cascade-SFT and Opus-4.6-Reasoning), stripping away conversational canopy and achieving a 72.6% overall word reduction across 2,633 rows.
- Target Fine-Tuning: We fine-tuned the final 2B target model (Occam-2B) on this optimized dataset using Unsloth LoRA on consumer-grade local hardware.
Tables
Table 1
| Metric | Original Words | Optimized Words | Reduction |
|---|---|---|---|
| logic_only_op_dataset (Opus-style) | 194.6 avg | 84.7 avg | 42.4% |
| logic_only_nvd_dataset (NVIDIA-style) | 444.4 avg | 106.5 avg | 67.2% |
| Overall (2633 examples) | 956,626 total | 261,820 total | 72.6% |
Table 2
| Subject | Base Accuracy | FT Accuracy | Improvement |
|---|---|---|---|
| Biology | 53.14% | 69.32% | +16.18% |
| Business | 43.60% | 52.98% | +9.38% |
| Chemistry | 51.59% | 55.74% | +4.15% |
| Computer Science | 39.76% | 48.29% | +8.54% |
| Economics | 49.41% | 56.87% | +7.46% |
| Engineering | 31.37% | 35.19% | +3.82% |
| Health | 37.16% | 46.33% | +9.17% |
| History | 26.25% | 33.86% | +7.61% |
| Law | 11.44% | 23.16% | +11.72% |
| Math | 56.18% | 60.62% | +4.44% |
| Other | 29.87% | 40.04% | +10.17% |
| Philosophy | 29.26% | 38.28% | +9.02% |
| Physics | 53.27% | 54.50% | +1.23% |
| Psychology | 41.60% | 55.39% | +13.78% |
Table 3
| Metric | Base Model | FT Model | Difference |
|---|---|---|---|
| Average Words | 830.3 | 297.6 | 64.2% fewer |
| Median Words | 651.0 | 242.5 | 62.7% fewer |
Impact: Precision Over Volume
By training on the MasterMind’s adapted trajectories, Occam-2B rewired its parametric behavior to prioritize immediate logical extraction.
Statistical Significance
Occam-2B achieved a statistically significant (P < 0.0001) absolute accuracy increase of +6.71% on the MMLU-Pro benchmark. Furthermore, it reduced the “Token Wall” failure state from 961 incidents (in the base model) down to just 137.
On the PhD-level GPQA Diamond benchmark, Occam-2B maintained competitive accuracy while using approximately 64% fewer tokens for its logical deductions. Ultimately, this proves that prioritizing logical structure over data volume enables small models to achieve exceptional reasoning precision.
Artifact Resources
- HuggingFace Collection: Occam-ClearCoT Models & Datasets
- Research Report: Clear Chain-of-Thought (ClearCoT) PDF